Up to 50x lower inference costs

Build AI data pipelines your team can trust

Sutro is a fully-managed, model-independent platform for aligning AI functions with your team’s judgment and running them at any scale. No prompt engineering, complex eval setup, or fine-tuning required. Fully hosted or in your own VPC.

Run on any model, including decision models.

  • OpenAI: GPT, GPT-OSS, and Luna Decisions
  • Claude
  • Gemini
  • Gemma
  • Qwen
  • NVIDIA Nemotron
  • DeepSeek
  • Z.ai GLM
  • TypeSafe Jev decision models
  • Cloudflare Clef decision models
Book a demo

Listing reviewer review_listing()

1 Align with your team’s judgment

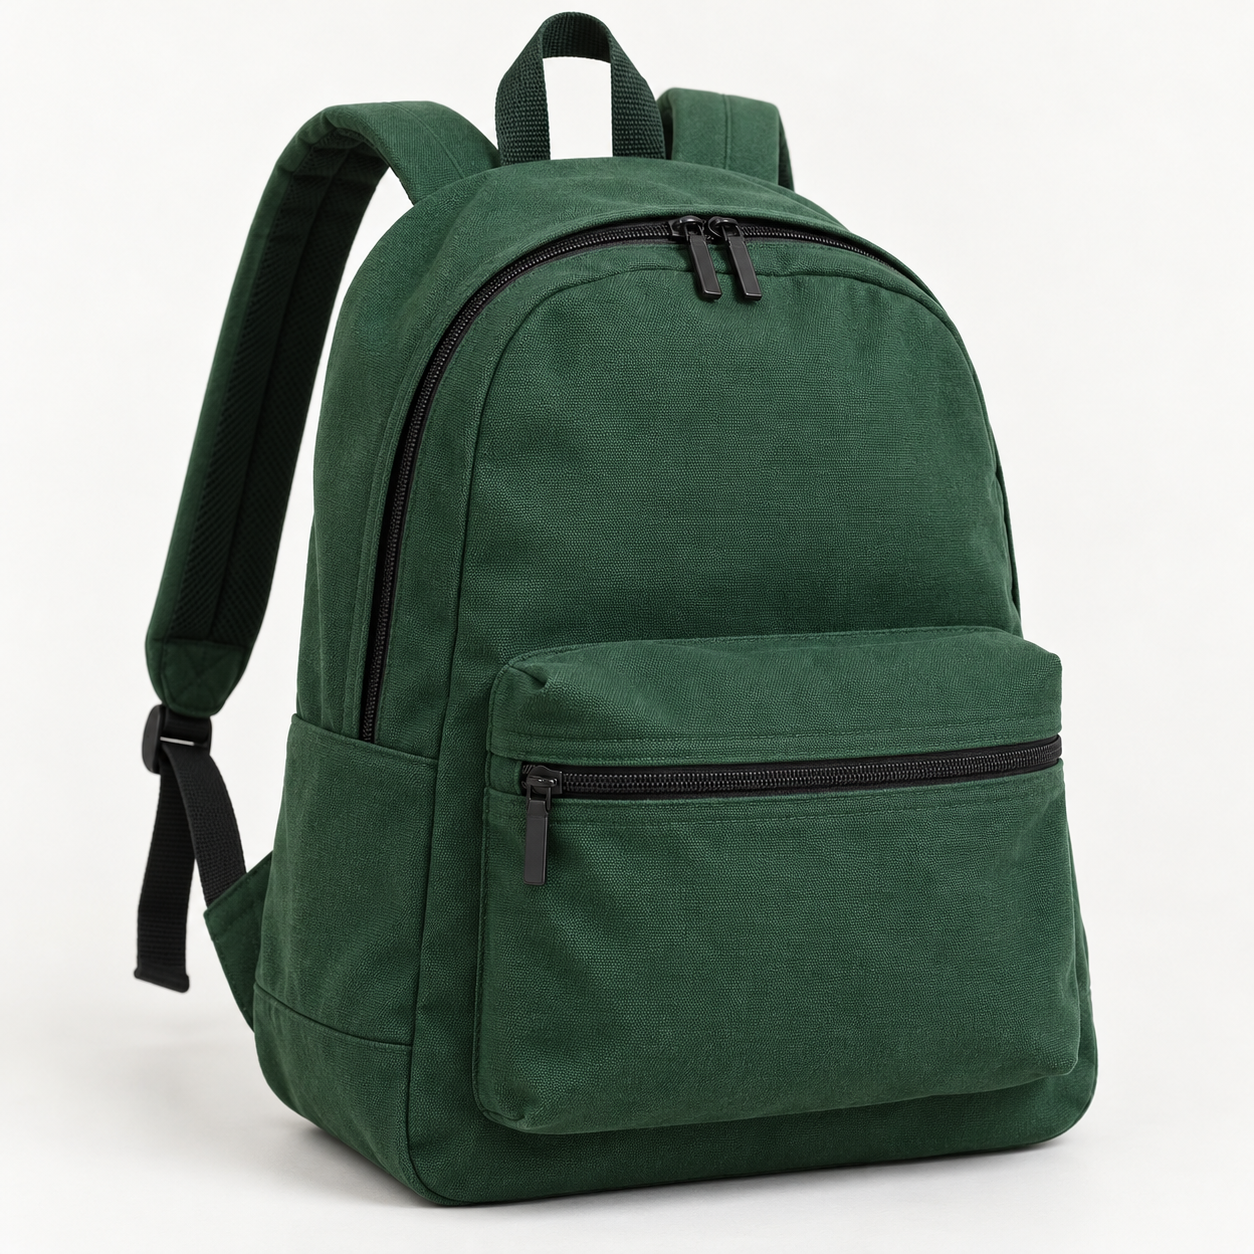
Forest-green canvas backpack with a front zip pocket on a neutral studio background
Label this example
Needs workReady
The product interior isn’t shown.
Example 1 of 3Expert agreement: 96.1% (+18.7 pts)

2 Always know the best models for your task

Selected model: Choose a modelQualityCost / 1K

3 Call your endpoint

import sutro as so

image = so.Image.from_file(
    "backpack.png"
)
result = so.run_function(
    "review_listing",
    {"image": image},
)
{
  "category": "backpack",
  "brand_fit": "on_brand",
  "listing_quality": "needs_work",
  "issues": [
    "Interior not shown"
  ]
}
19,573 processed$29.36Last 30 days
Lead scorer score_lead()

1 Align with your team’s judgment

Northstar Health

northstarhealth.example / about-us “better care starts before the visit” HQ: Austin, TX | team: ~240? (LinkedIn says 201–500) Healthcare workflow software for multi-site clinics; intake forms, scheduling, reminders + EHR integrations. CRM notes / updated Tue: sells to ops teams, NOT a care provider. Series B per old deck. Hiring implementation + enterprise AE roles. From website footer: patient engagement / reduce no-shows / HIPAA-ready workflows. Outbound notes: 3 locations mentioned in case study; customer count unconfirmed. See duplicate account “Northstar Hlth” before routing. Tech: API docs, Salesforce integration, calendar sync. Buyer likely VP Operations. Contact history still needs deduping.

Label this example
Strong fitWeak fit
Healthcare software vendor, not a care provider.
Example 1 of 3Expert agreement: 94.2% (+43.6 pts)

2 Always know the best models for your task

Selected model: Choose a modelQualityCost / 1K

3 Run on your full dataset

import sutro as so

job = so.batch_run_function(
    name="score_lead",
    data="prospect_database.csv",
)
results = so.await_job_completion(job)
{
  "company": "Northstar Health",
  "fit": "strong",
  "priority": "high",
  "reason": "Matches our target industry and company size."
}
prospect_database.csv · 13,789,571 records84% complete
11,589,167 processed$139.07

Candidate reviewer review_candidate()

1 Align with your team’s judgment

Morgan Lee

RESUME_final_v3 (2).pdf — copied text MORGAN LEE | Senior Software Engineer [email protected] / portfolio available EXPERIENCE 2023–present Northline / Sr SWE — data platform • Owned ingestion jobs + on-call; Python / SQL; migrated legacy pipelines, “~40% fewer failures” 2019 - 2023 Software Engineer Built APIs, distributed processing & internal analytics. Stack listed elsewhere: postgres, Kafka, Python3, SQL. EDUCATION: B.S. Computer Science SKILLS / Python, SQL, distributed systems [page 2] Projects: event ingestion service; warehouse migration. Formatting lost in export. Six years of professional engineering experience as of this resume.

Label this example
SeniorManager
Six years of engineering; no direct reports documented.
Example 1 of 3Expert agreement: 91.6% (+11.2 pts)

2 Always know the best models for your task

Selected model: Choose a modelQualityCost / 1K

3 Run on your full dataset

import sutro as so

job = so.batch_run_function(
    name="review_candidate",
    data="candidate_resumes.csv",
)
results = so.await_job_completion(job)
{
  "years_experience": 6,
  "role_fit": "strong",
  "seniority": "senior",
  "summary": "Strong platform experience; leadership scope unclear."
}
candidate_resumes.csv · 400,000 records64% complete
256,429 processed$3.08
“Sutro gives us a framework to develop judges that we have faith in.”
Sr. Software Engineer+60%Accuracy−94%Inference cost64 annotations per function
“Sutro saves our team countless hours, and it gives us the invaluable ability to measure, optimize, and prevent regressions against our domain expertise.”
CTOAI Data Marketplace+28%Accuracy−73%Inference cost163 annotations per function
“Sutro unlocks use cases that weren't previously possible from a cost perspective.”
Principal Data Platform Engineer+18%Accuracy−98%Inference cost30 annotations per function

*Average per customer function.

Request customer case studies

Why you'll love it

Forget prompts, fine-tuning, and evals

Just upload a sample of your data, give feedback on a handful of examples, and watch quality climb automatically.

Evaluation quality
Quality climbs with your feedback Illustrative example: quality increases from a 50% seed prompt to 57%, 78%, 81%, and 93% over four iterations. Each iteration adds 10 annotations, for 40 total and a 43 percentage point improvement. The dashed line shows seed prompt quality. 100%75%50% 10 annotations10 annotations 30 annotations30 annotations 93% 50% Seed1234 Iteration

Never get locked into a model

Run your tasks on any AI model. Sutro helps you find the best fit for your quality and cost needs, and easily switch when new models come out.

Cost–quality frontier
The Pareto-efficient cost–quality frontier October 29, 2026 lead-strength sweep, with a linked November 5 Haiku-only repair: 9 models evaluated on the same 70 labeled examples (38 human labels and 32 consensus labels). Jev 1.14, GPT-6 Luna Decisions, Gemma 4 26B A4B, and Claude Haiku 5.5 form the cost–quality frontier. Clef scores 87.1%. Haiku ties DeepSeek for highest measured accuracy at 90.0%, at a lower cost. Costs use a logarithmic scale and the sweep’s recorded average cost per call. 75% 80% 85% 90% 95% $0.10 $0.50 $2 $10 AccuracyCost / 1K records · log scale Gemma 4 26B A4B: 87.1% accuracy; $0.325 / 1K records Clef: 87.1% accuracy; $0.631 / 1K recordsClef GPT-6 Luna Decisions: 84.3% accuracy; $0.255 / 1K recordsLuna Decisions Jev 1.14: 82.9% accuracy; $0.120 / 1K recordsJev 1.14 Claude Haiku 5.5: 90.0% accuracy; $0.668 / 1K records DeepSeek V4.1 Flash: 90.0% accuracy; $1.667 / 1K records GLM 5.3 Flash: 84.3% accuracy; $1.578 / 1K records Gemini 3.8 Flash: 84.3% accuracy; $4.398 / 1K records GPT-6.1 Sol: 85.7% accuracy; $12.403 / 1K records Claude Haiku 5.5Best90.0% · $0.67 / 1K records Gemma 4 26BValue87.1% · $0.33 / 1K records

Surprisingly affordable

Run millions of AI tasks for the price of a coffee run. Unlock use cases that seemed out of reach, while raising the quality bar.

Before
1042 · support✓
1043 · billing✓
$0
0 records processed
After
1042 · support✓
1043 · billing✓
$0
0 records processed

How it works

Define and Align

Sutro surfaces hard cases for your experts to annotate - then optimizes directly against their feedback.

app.sutro.sh/functions/lead-qualifier
Optimize
Collecting feedback · 1/3
Is this company a good fit for our sales team?
Example 1 of 3

Cedar Labs · website + CRM export

industry: Software Development | employees: 201–500
site: “Your embedded product team. We design & build for clients.”
crm_note: “SaaS? AE to confirm” | enrichment: B2B Software
pricing: project-based; no subscription product found
Is this a qualified lead?Reviewing example

Model Sweeps

Benchmark models on your task to build your own frontier of cost and quality. See which models deliver the best quality for your budget, then choose the tradeoff that works for you. Redraw your task frontier with a single click when new models are released.

The Pareto-efficient cost–quality frontier October 29, 2026 lead-strength sweep, with a linked November 5 Haiku-only repair: 12 models evaluated on the same 70 labeled examples (38 human labels and 32 consensus labels). Jev 1.14, GPT-6 Luna Decisions, Gemma 4 26B A4B, and Claude Haiku 5.5 form the cost–quality frontier. Clef scores 87.1%. Haiku ties DeepSeek for highest measured accuracy at 90.0%, at a lower cost. Costs use a logarithmic scale and the sweep’s recorded average cost per call. 75% 80% 85% 90% 95% $0.10 $0.50 $2 $10 AccuracyCost / 1K records · log scale DeepSeek V4.1 Flash: 90.0% accuracy; $1.667 / 1K records GPT-OSS 120B: 87.1% accuracy; $0.636 / 1K records Gemma 4 26B A4B: 87.1% accuracy; $0.325 / 1K records Clef: 87.1% accuracy; $0.631 / 1K recordsClef GPT-6 Luna: 85.7% accuracy; $0.655 / 1K records GPT-6.1 Sol: 85.7% accuracy; $12.403 / 1K records GLM 5.3 Flash: 84.3% accuracy; $1.578 / 1K records Gemma 4 31B: 84.3% accuracy; $0.356 / 1K records Gemini 3.8 Flash: 84.3% accuracy; $4.398 / 1K records GPT-6 Luna Decisions: 84.3% accuracy; $0.255 / 1K recordsLuna Decisions Jev 1.14: 82.9% accuracy; $0.120 / 1K recordsJev 1.14 Claude Haiku 5.5: 90.0% accuracy; $0.668 / 1K records Claude Haiku 5.5Best90.0% · $0.67 / 1K records Gemma 4 26BValue87.1% · $0.33 / 1K records

Scale

Run your function where you see fit: on your own inference providers, or using Sutro's ultra cost-efficient batch inference service. Process millions of rows and billions of tokens at a time.

score_leads("prospect_database.csv")Auto-scaling
One function, millions of rows As a dataset grows, copies of the same function run in parallel. Each input row maps to its own output row. ƒ ƒ ƒ ƒ ƒ ƒ ⋮ ⋮ ⋮
13,789,571 records

Optimize tasks, not models.

Models change fast. Keep your task, judgment, and evals intact while Sutro finds your best quality–cost options. Choose a model yourself, or let Sutro choose.

Lead qualificationToday
Quality ↑Cost → Jev Gemma Luna Decisions Haiku DeepSeek GPT-OSS Clef Luna Sol GLM Gemma Gemini

Bring your task, data, and judgment. Sutro handles the rest.

  • Finding GPUs💰💰
  • New model release!
  • Evals
    × 6 checks failing
  • Prompt versions
  • External annotators💰
  • Hugging FaceModel fine-tunes
  • Labeled datasets
  • Eval reports
    85.7% ↓ 3.2 pts
  • Model APIs
    401 Unauthorized
  • Google SheetsModel output spreadsheets
  • Retry queues
    429 · 128 queued
  • Inference scaling
  • Monitoring
    p95 4.8s
  • Built-in evals
  • Automated harness optimization
  • Throughput-optimized inference
  • Centralized task management
  • Continuous model comparison
  • API, SDK, and MCP access
  • Fully hosted or in your own VPC

Pricing that scales with you

All plans include a free two-week trial.

Book a demo

Starter

$50 / month

Includes $10/month in usage credits
  • Up to 2 deployed functions
  • 5 saved functions
  • Additional usage billed separately

Scale

$500 / month

Includes $100/month in inference credits
  • Up to 25 deployed functions
  • Unlimited saved functions
  • Additional usage billed separately
Book a demo

Enterprise

Custom

Pre-paid inference discounts available
  • Self-hosted options available
  • Integrate with your own providers
  • Advanced support and deployed engineering plans
Talk to sales

Batch inference · Open-weight models

Machine-time pricing means you only pay for the compute your workload actually consumes. Data can be read from your own S3-compatible storage.

Estimated price $120
Number of records 10 million
Average uncached input size

Frequently asked

Is this an evals product?

Evaluation is part of Sutro, but it’s not the whole product. Sutro turns expert feedback into optimized, reusable AI Functions that can run on any model and at any scale.

How does Sutro’s inference work?

Sutro offers a managed, high-throughput batch inference service for running Functions on open-source models.

Using Sutro’s inference is optional. Functions can also run in real time on any provider you choose, or be exported for local or edge inference.

How does Sutro work with decision models like Jev and Clef?

Sutro helps you teach models your team’s standards, compare their quality and cost, and turn them into reusable AI Functions. Decision models like Jev and Clef can power those Functions when the task calls for structured choices rather than free-form text.

Can Sutro use image inputs and other modalities? Can it call tools?

Yes. Sutro supports images, PDFs, and web search capabilities today. Additional modalities and custom tool calling are available on a per-request basis.

What models does Sutro use?

Sutro is model-agnostic, and we support a mix of open-source and proprietary models. Small, open-source models commonly outperform larger proprietary models on expert-aligned data processing tasks. Sutro helps automatically find the best model for your needs.

Can I self-host Sutro? Do you support BYOC and BYOK?

Yes. Sutro can be managed as SaaS or entirely self-hosted. You can bring your own provider keys and cloud credentials in either case.

How does Sutro compare to prompt engineering, fine-tuning, or RL?

Sutro is designed to be more robust, accurate, and scalable than prompt engineering, and more data efficient, portable, and re-trainable than fine-tuning or RL. We encourage you to try it out and see for yourself!

What will you scale with Sutro?

Get Started

Join the self-serve waitlist

What are your bottlenecks? (Select any that apply)